SimpliSmart high-performance AI inference 01 · The challenge
Machine learning engineers don't read marketing prose. They look at latency percentiles, GPU utilization, and cost per million tokens.
Every AI infrastructure company claims to offer 'blazing fast inference'. But when enterprise teams evaluate inference platforms for production GenAI applications, they benchmark with real model weights: Llama 3, Mistral, Stable Diffusion, and custom embeddings.
Latency vs throughput benchmark graphs 02 · The architecture of speed
Making compiler-level breakthroughs visually legible
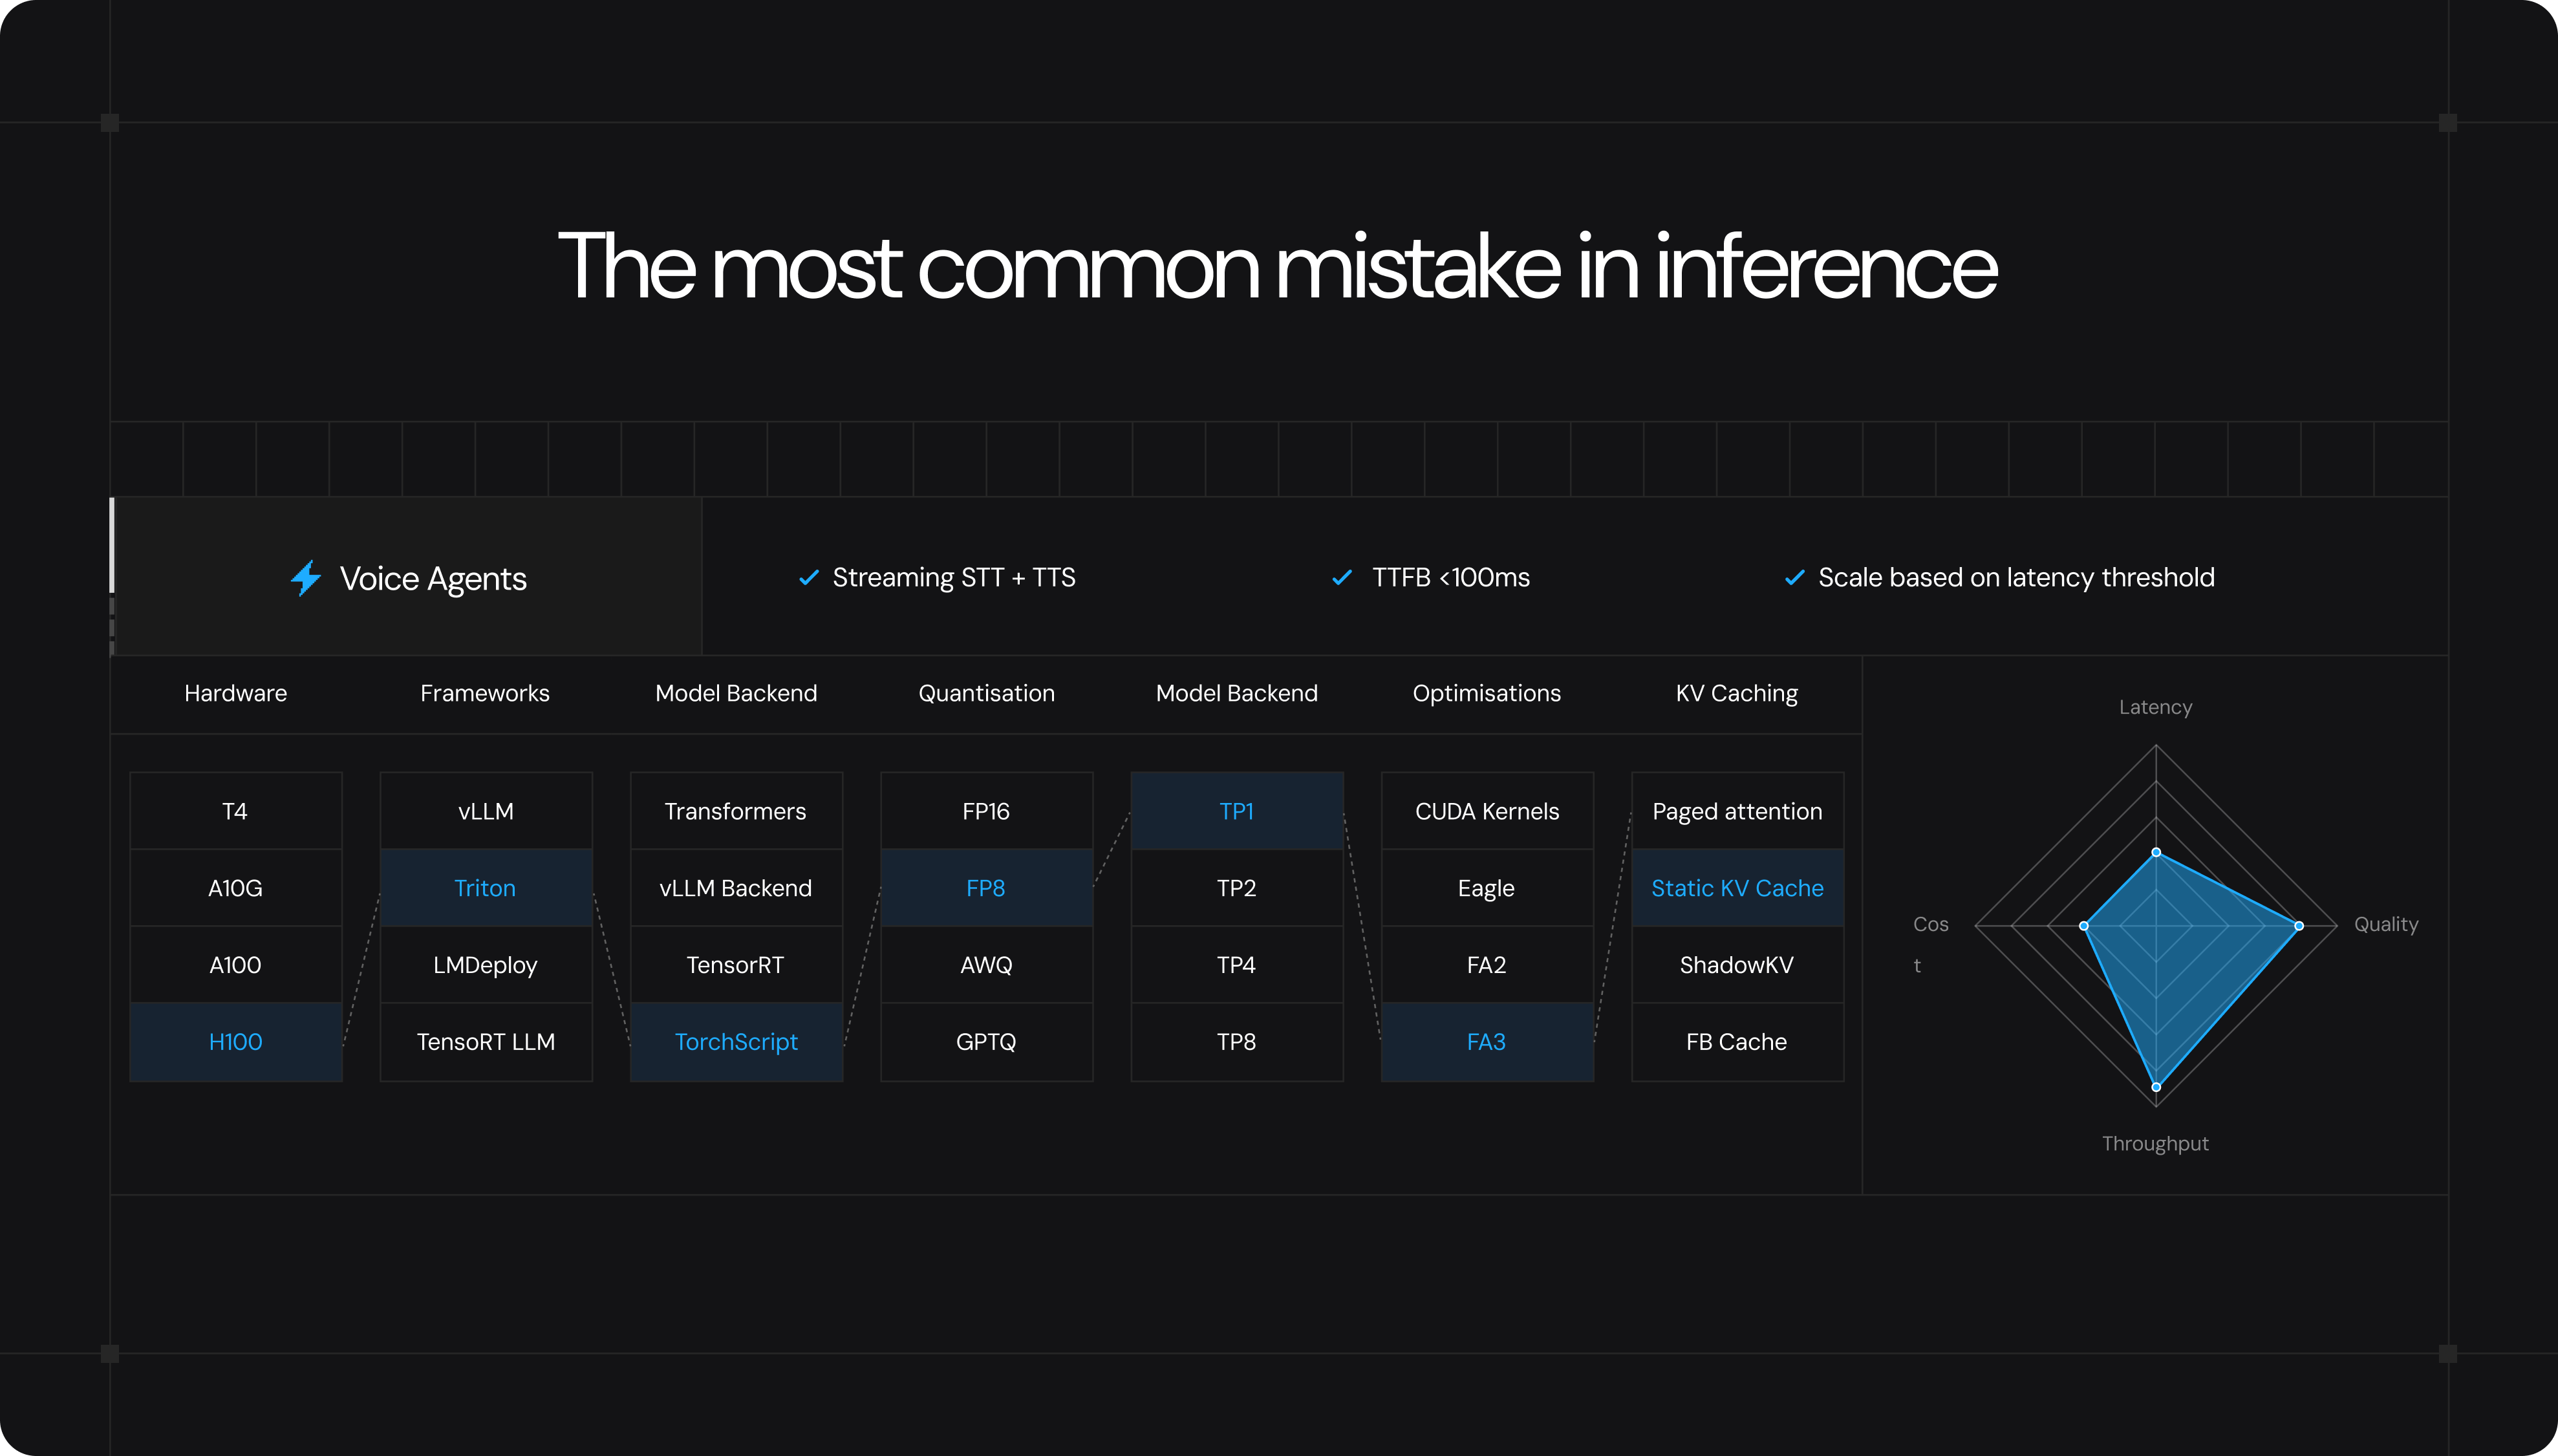
SimpliSmart's secret sauce isn't buying more GPUs; it's software-level optimization. Dynamic batching, kernel tuning, and memory allocation algorithms that squeeze maximum FLOPS out of NVIDIA H100 and A100 clusters.
Software optimization architectural stack 
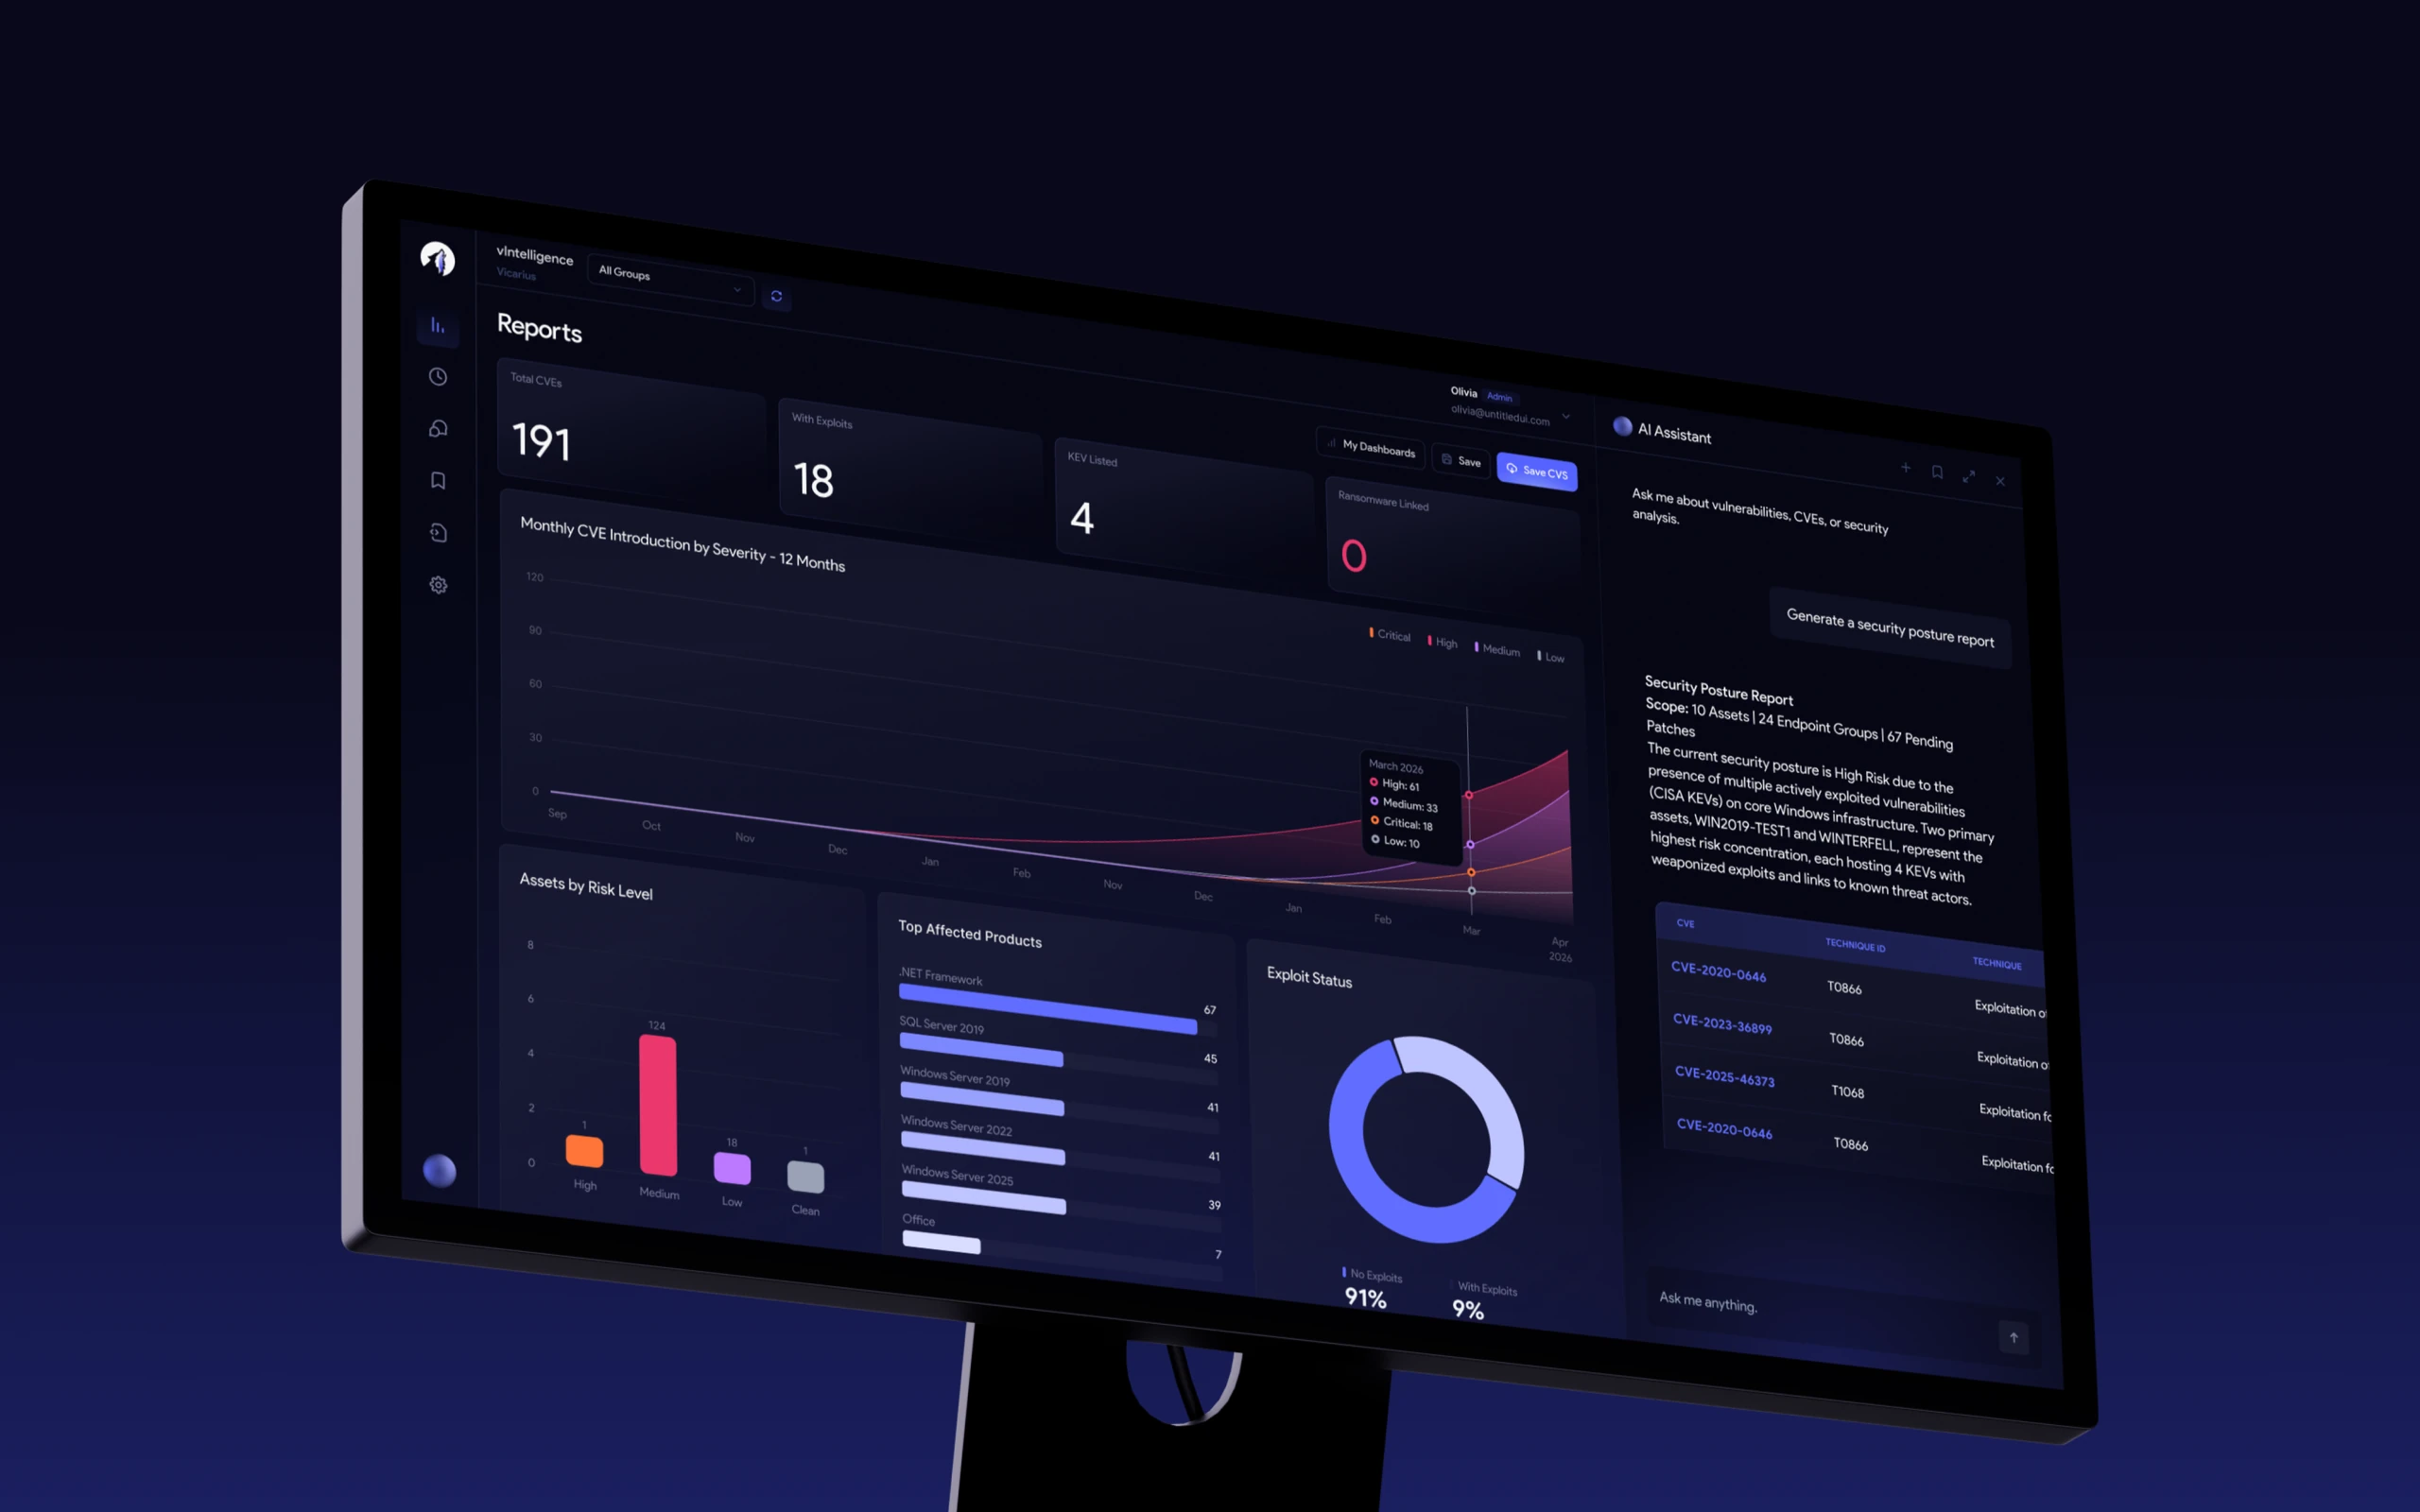
Inference cluster dashboard and model 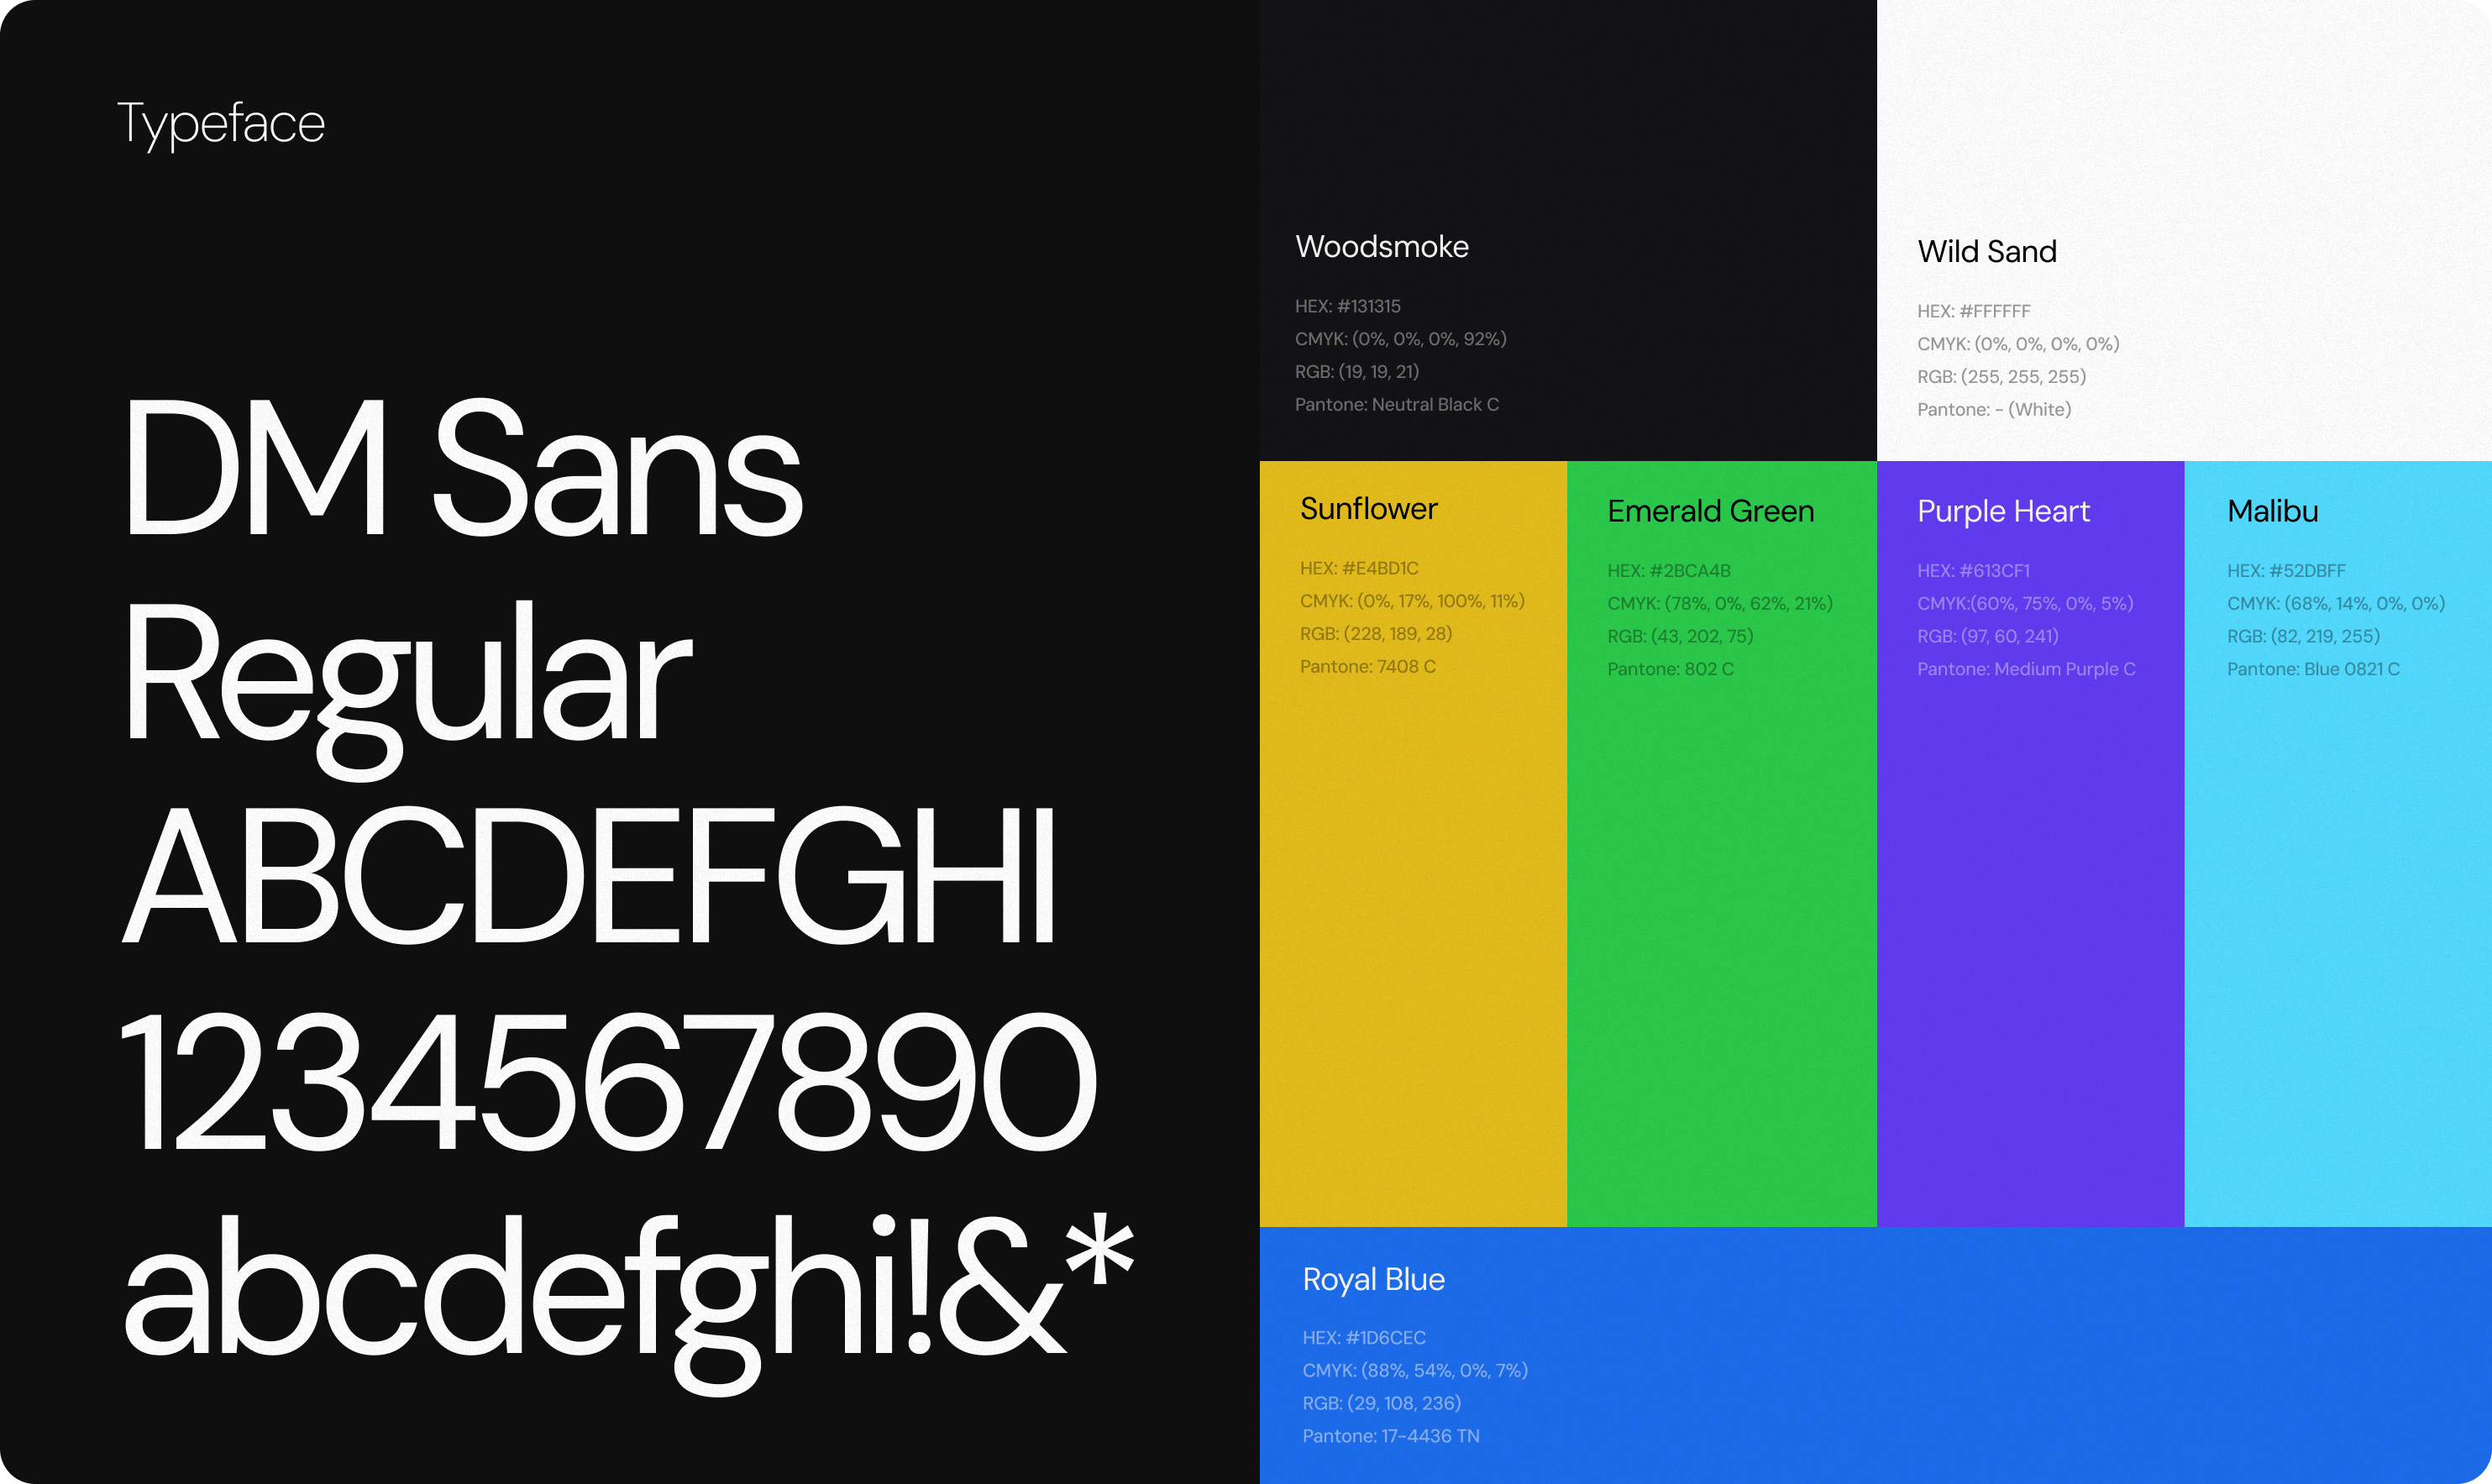
Hardware utilization metrics comparing 03 · Developer experience & brand system
Engineered for teams who live in terminal windows
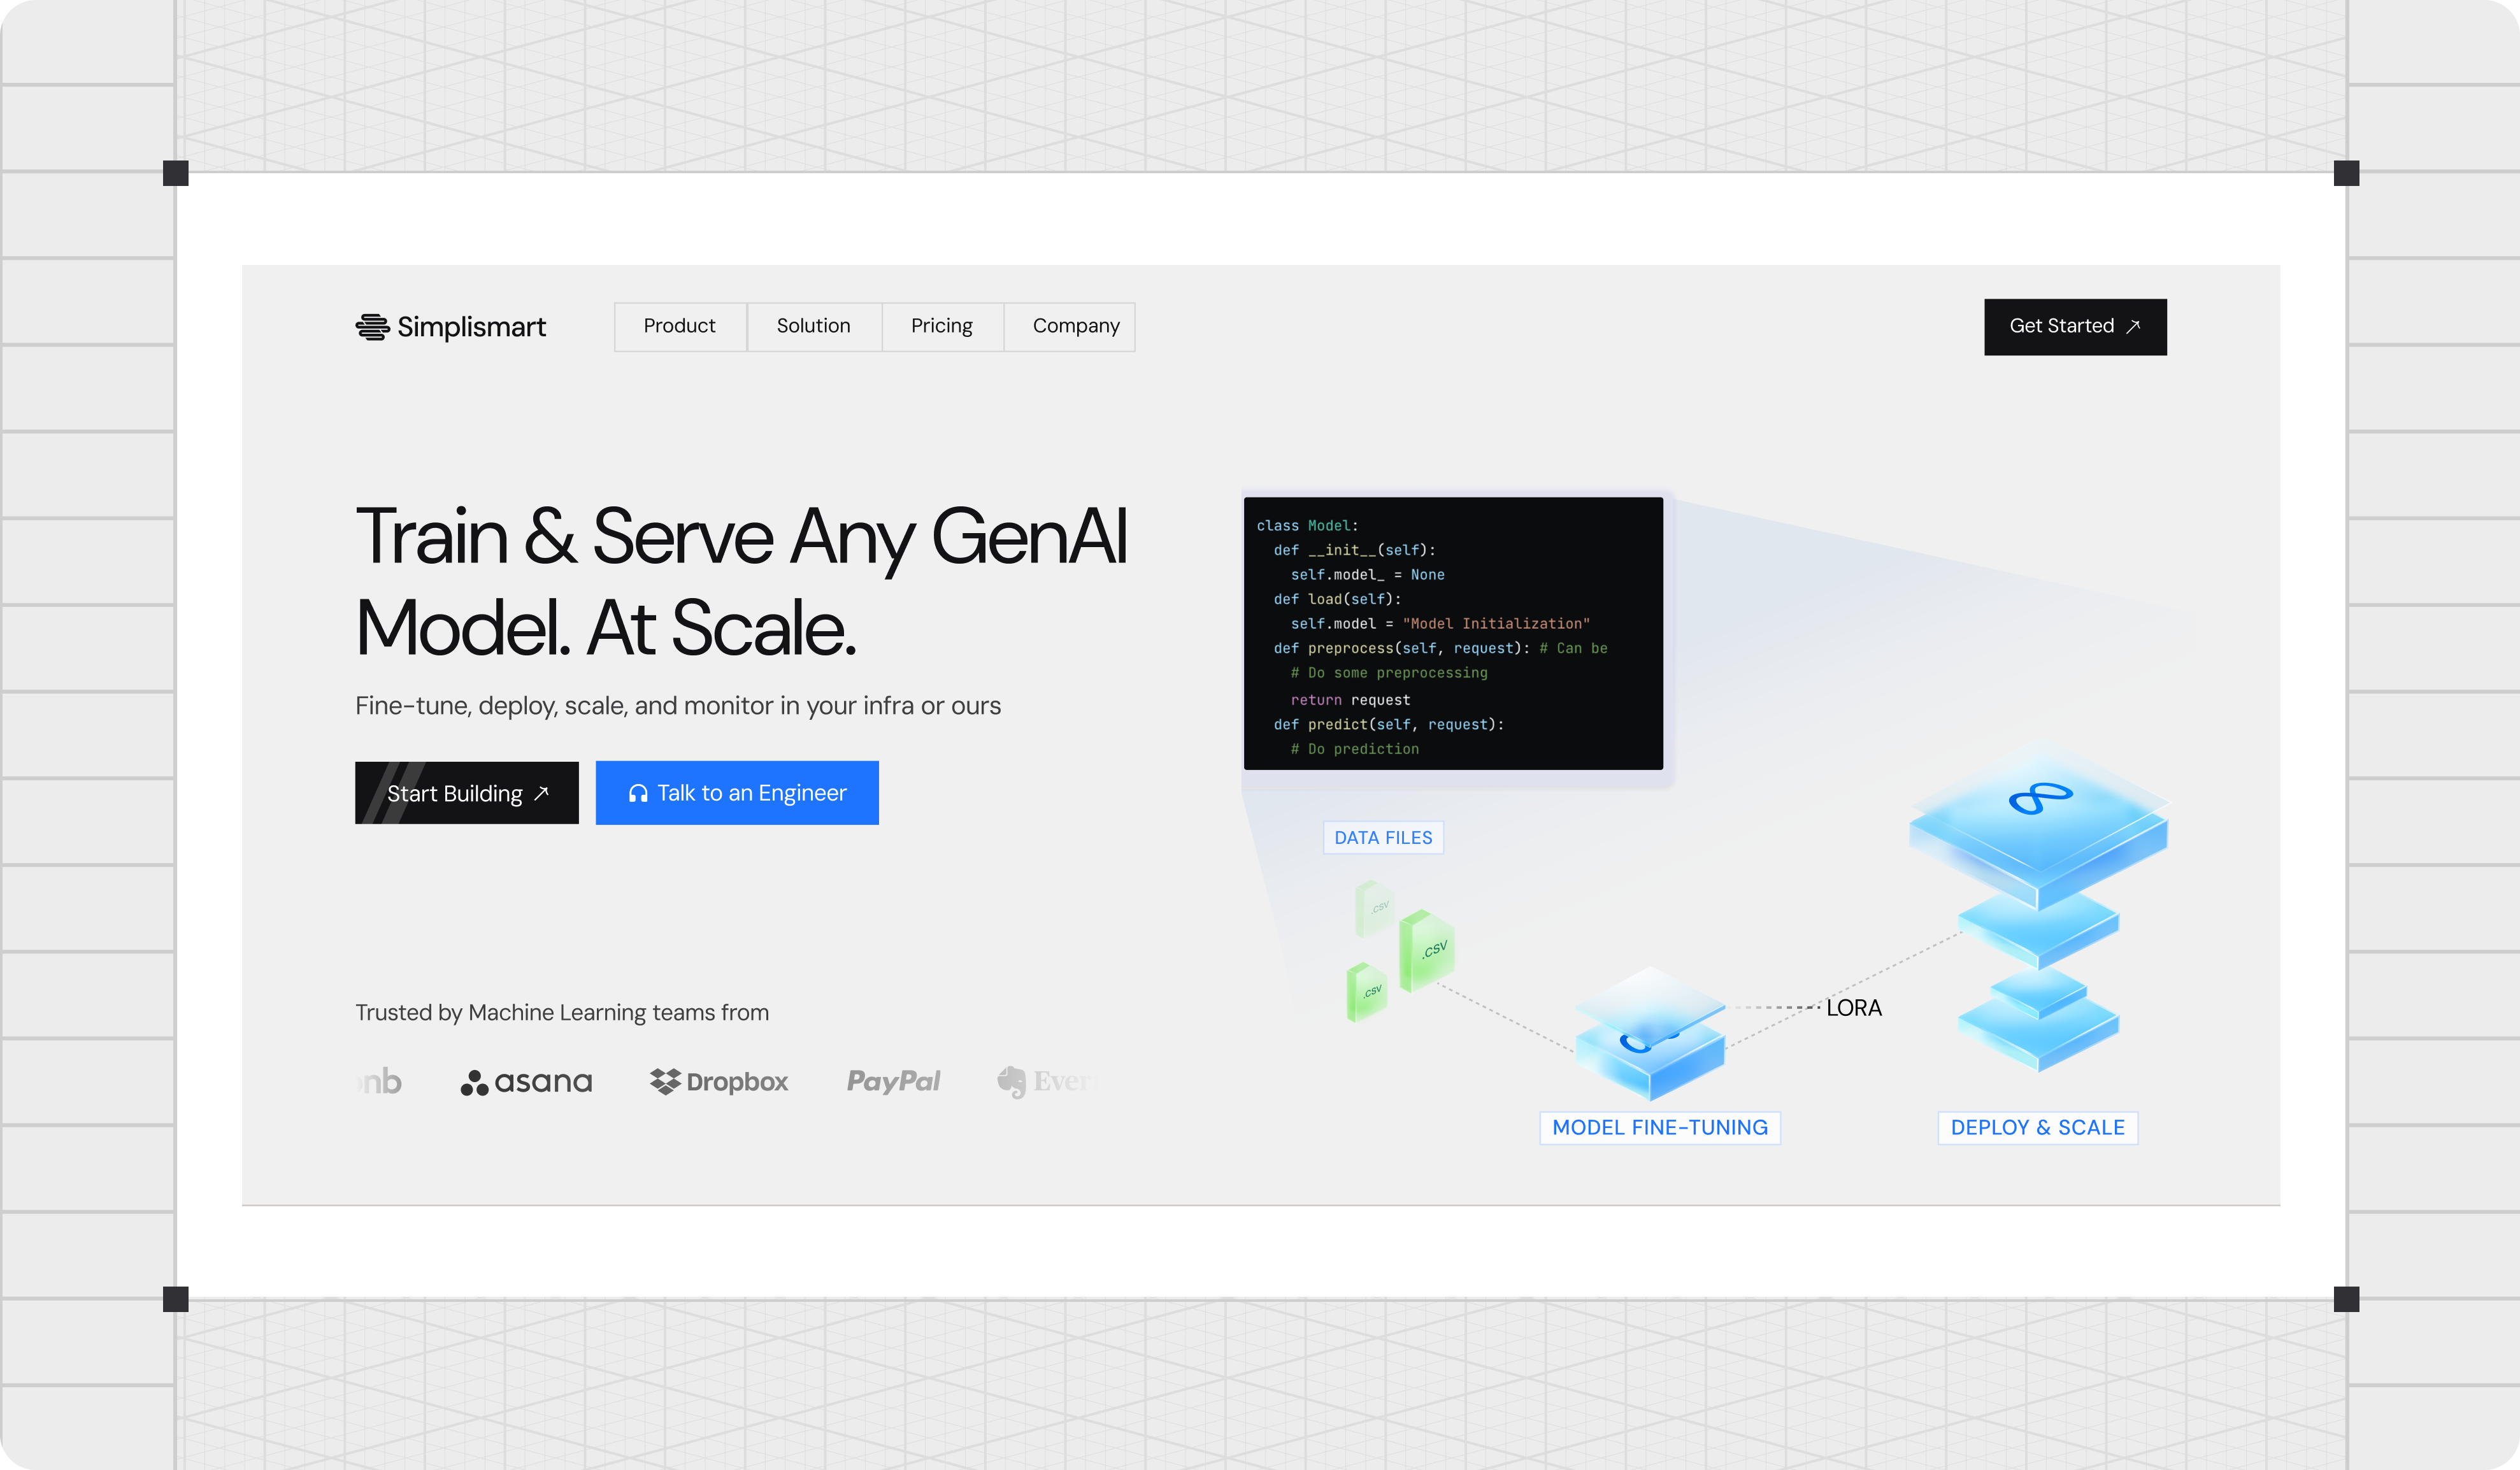
We built the brand around a technical cobalt and deep indigo palette, supported by crisp monospace typography and interactive code snippets.
Developer API documentation and real-time 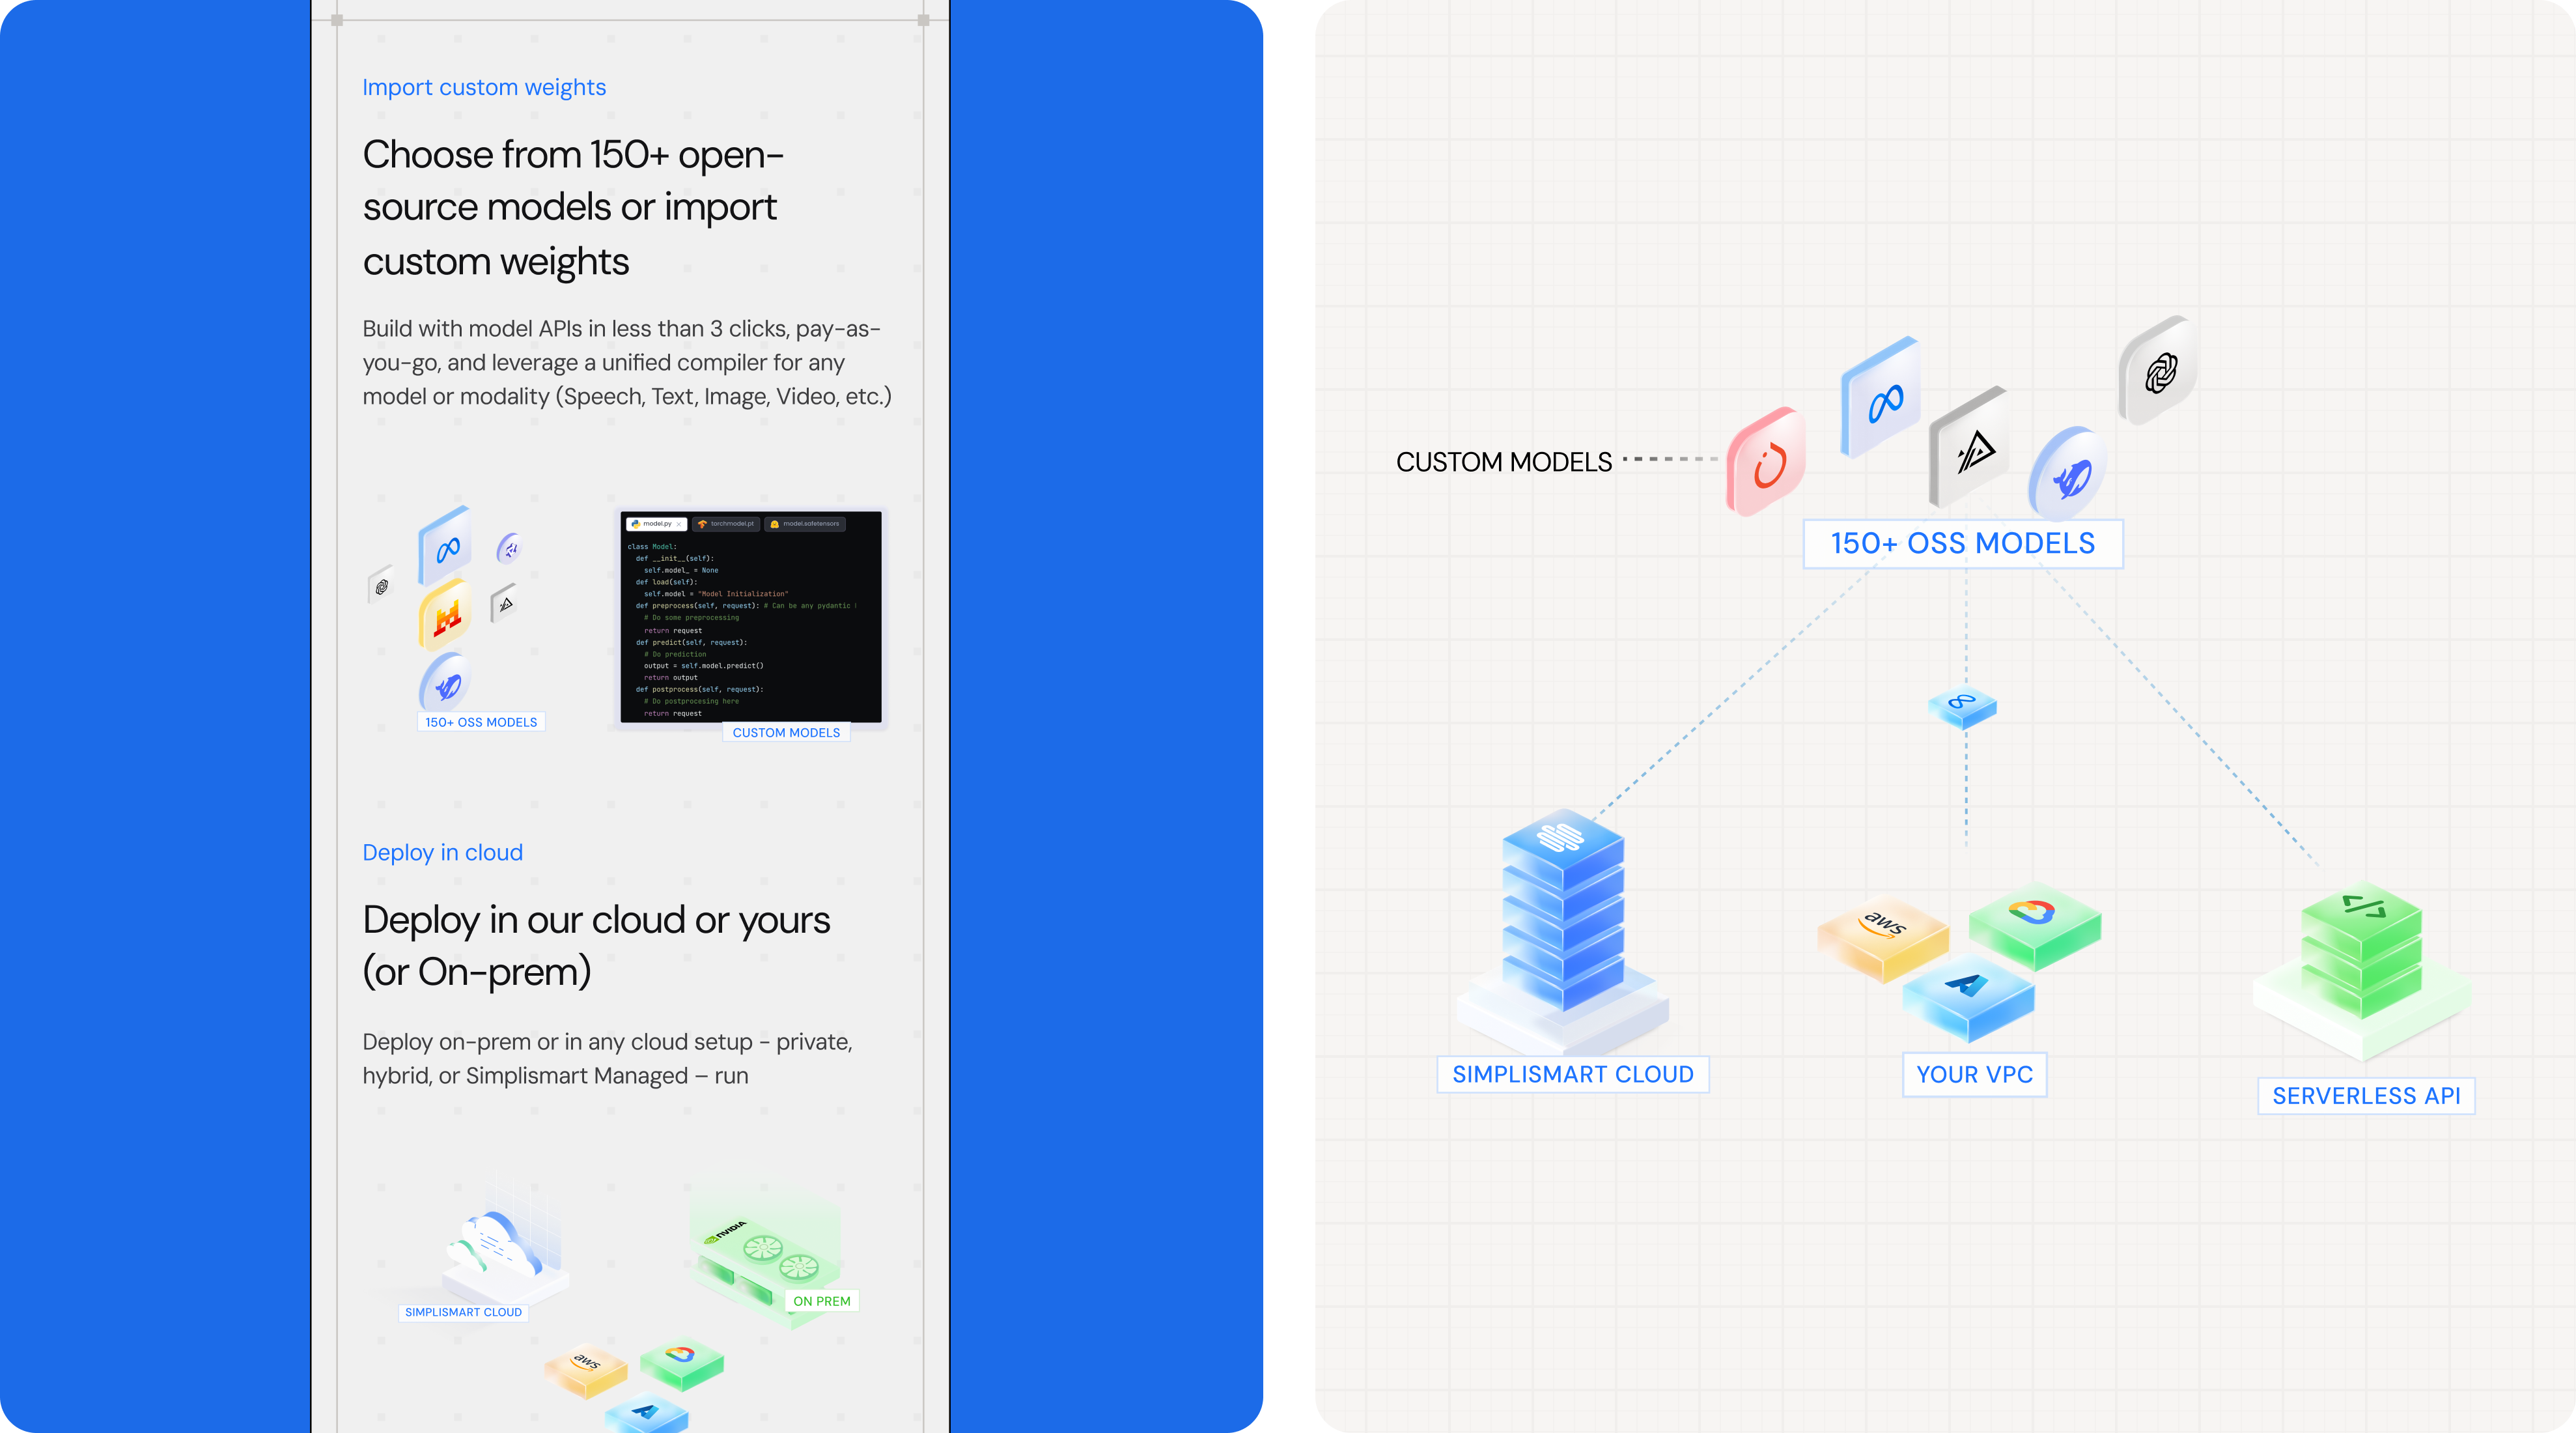
Python SDK integration code and one-line 
Enterprise security and VPC private cloud 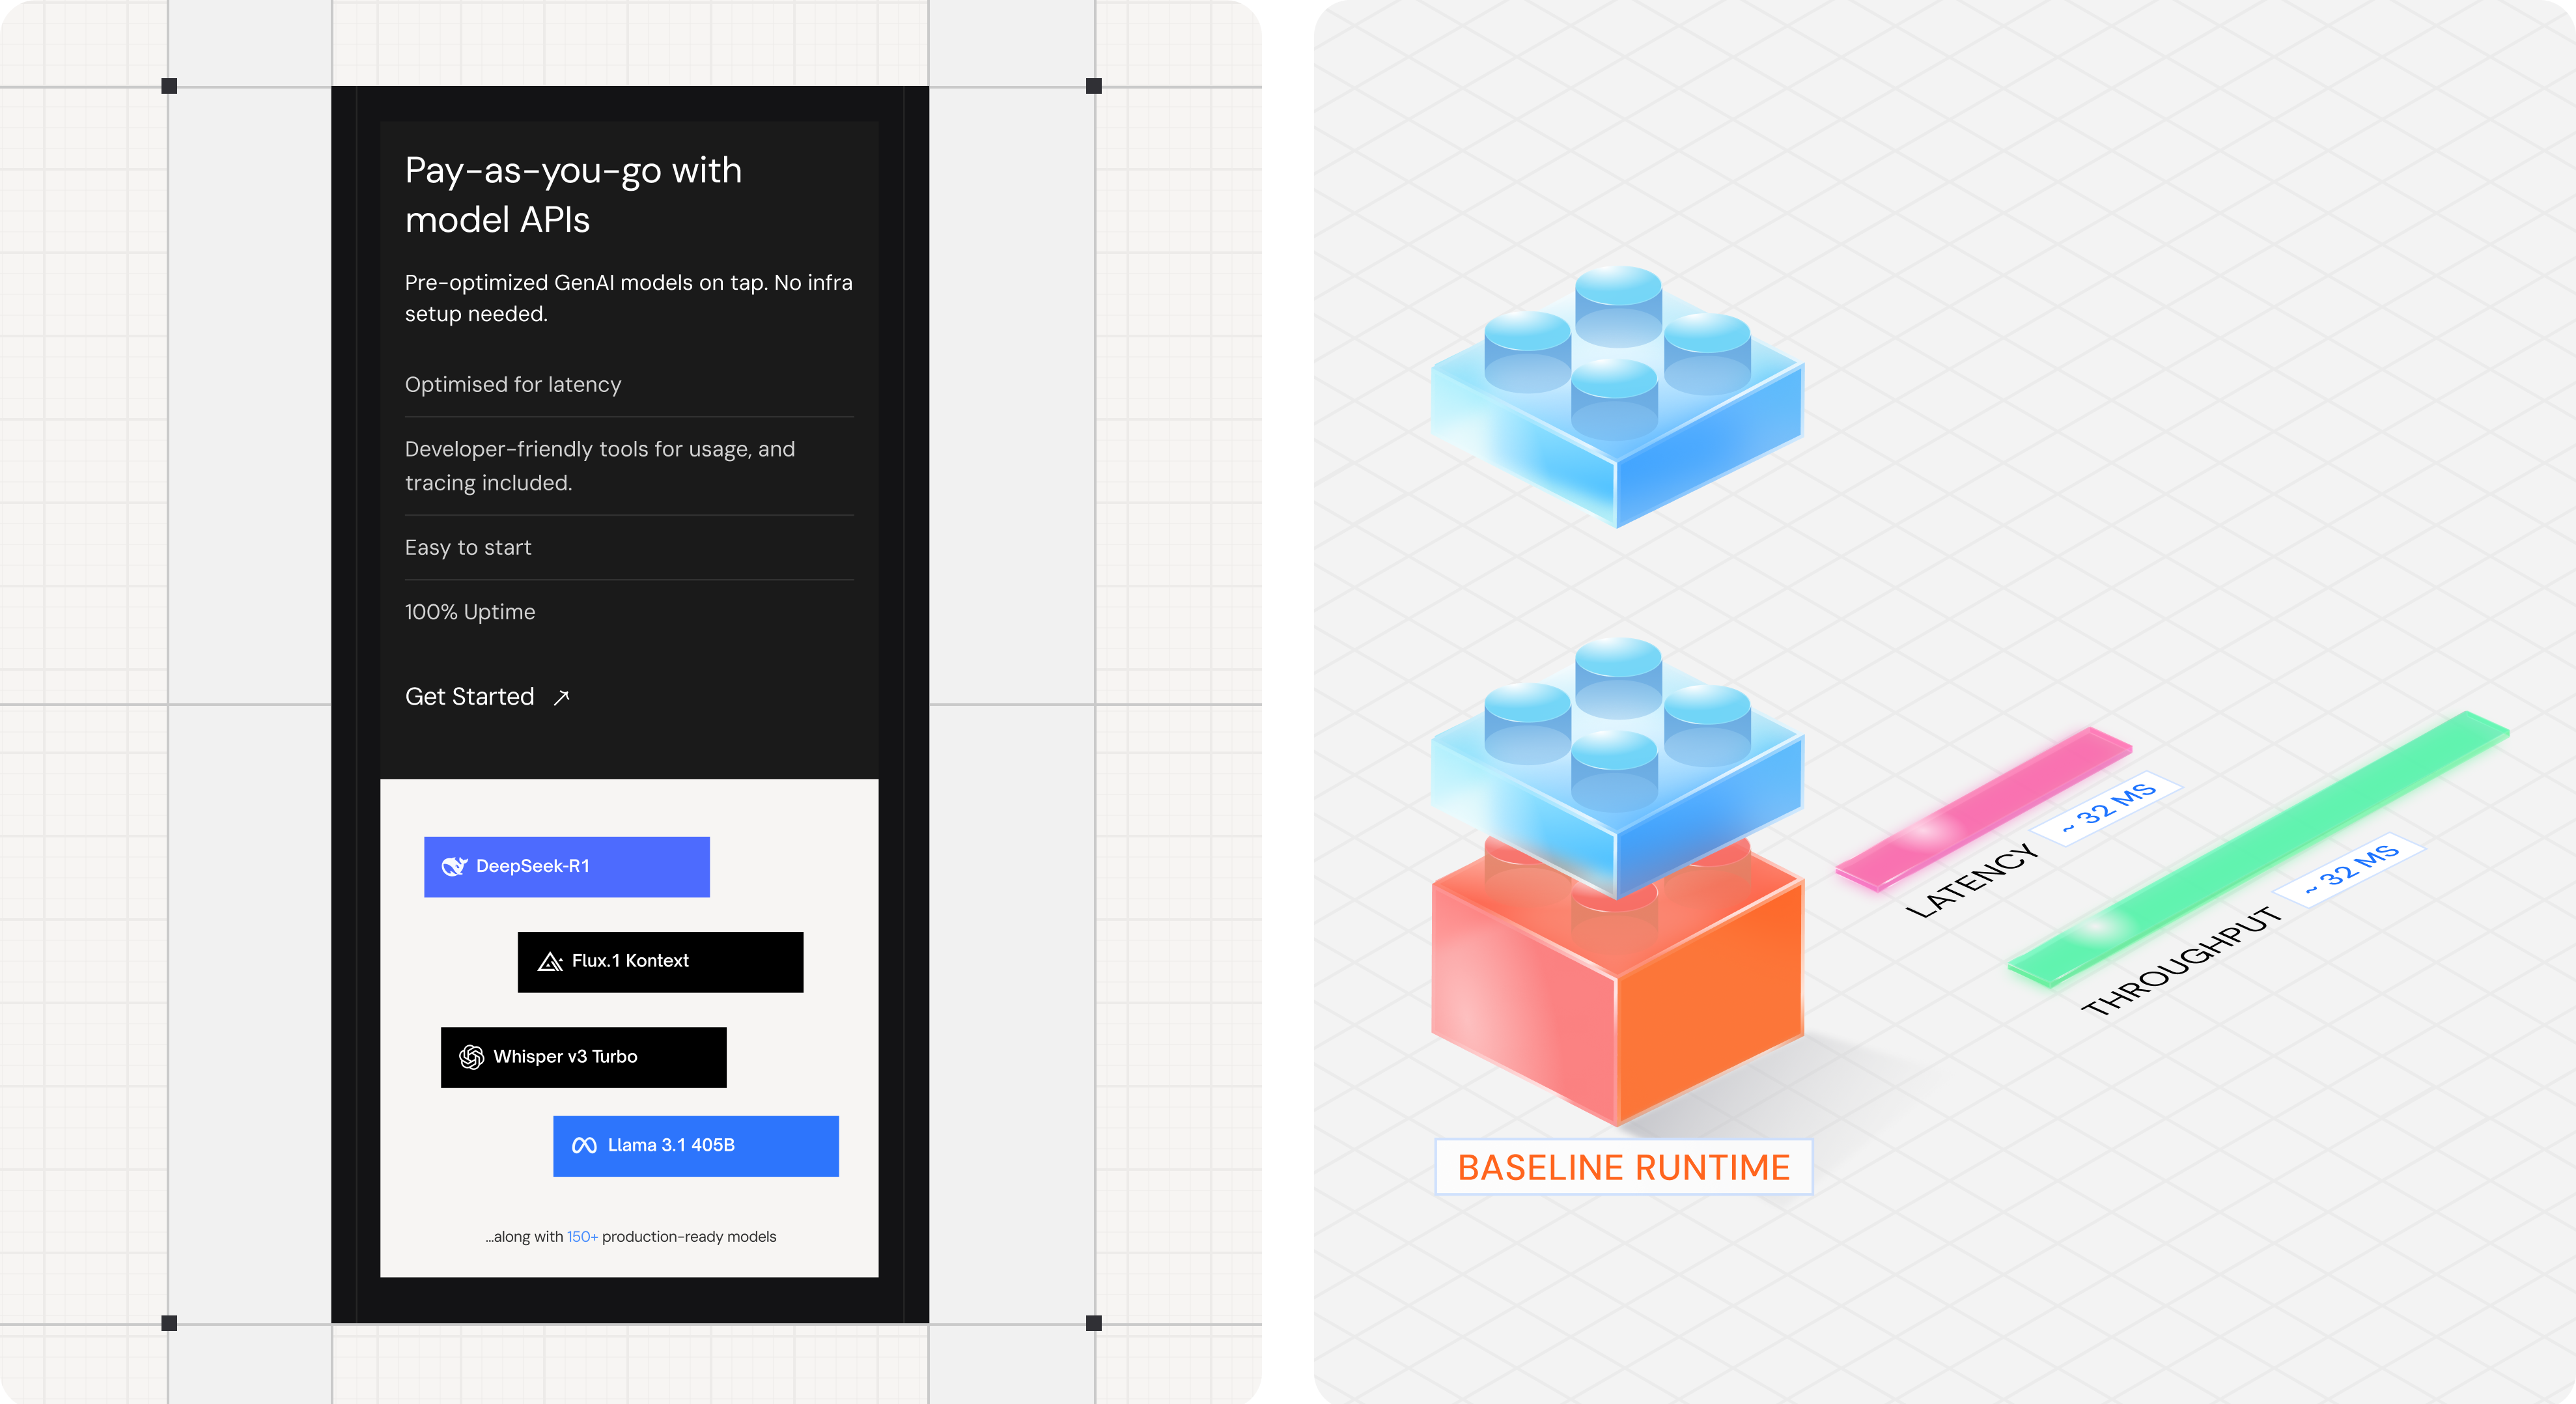
Brand identity system 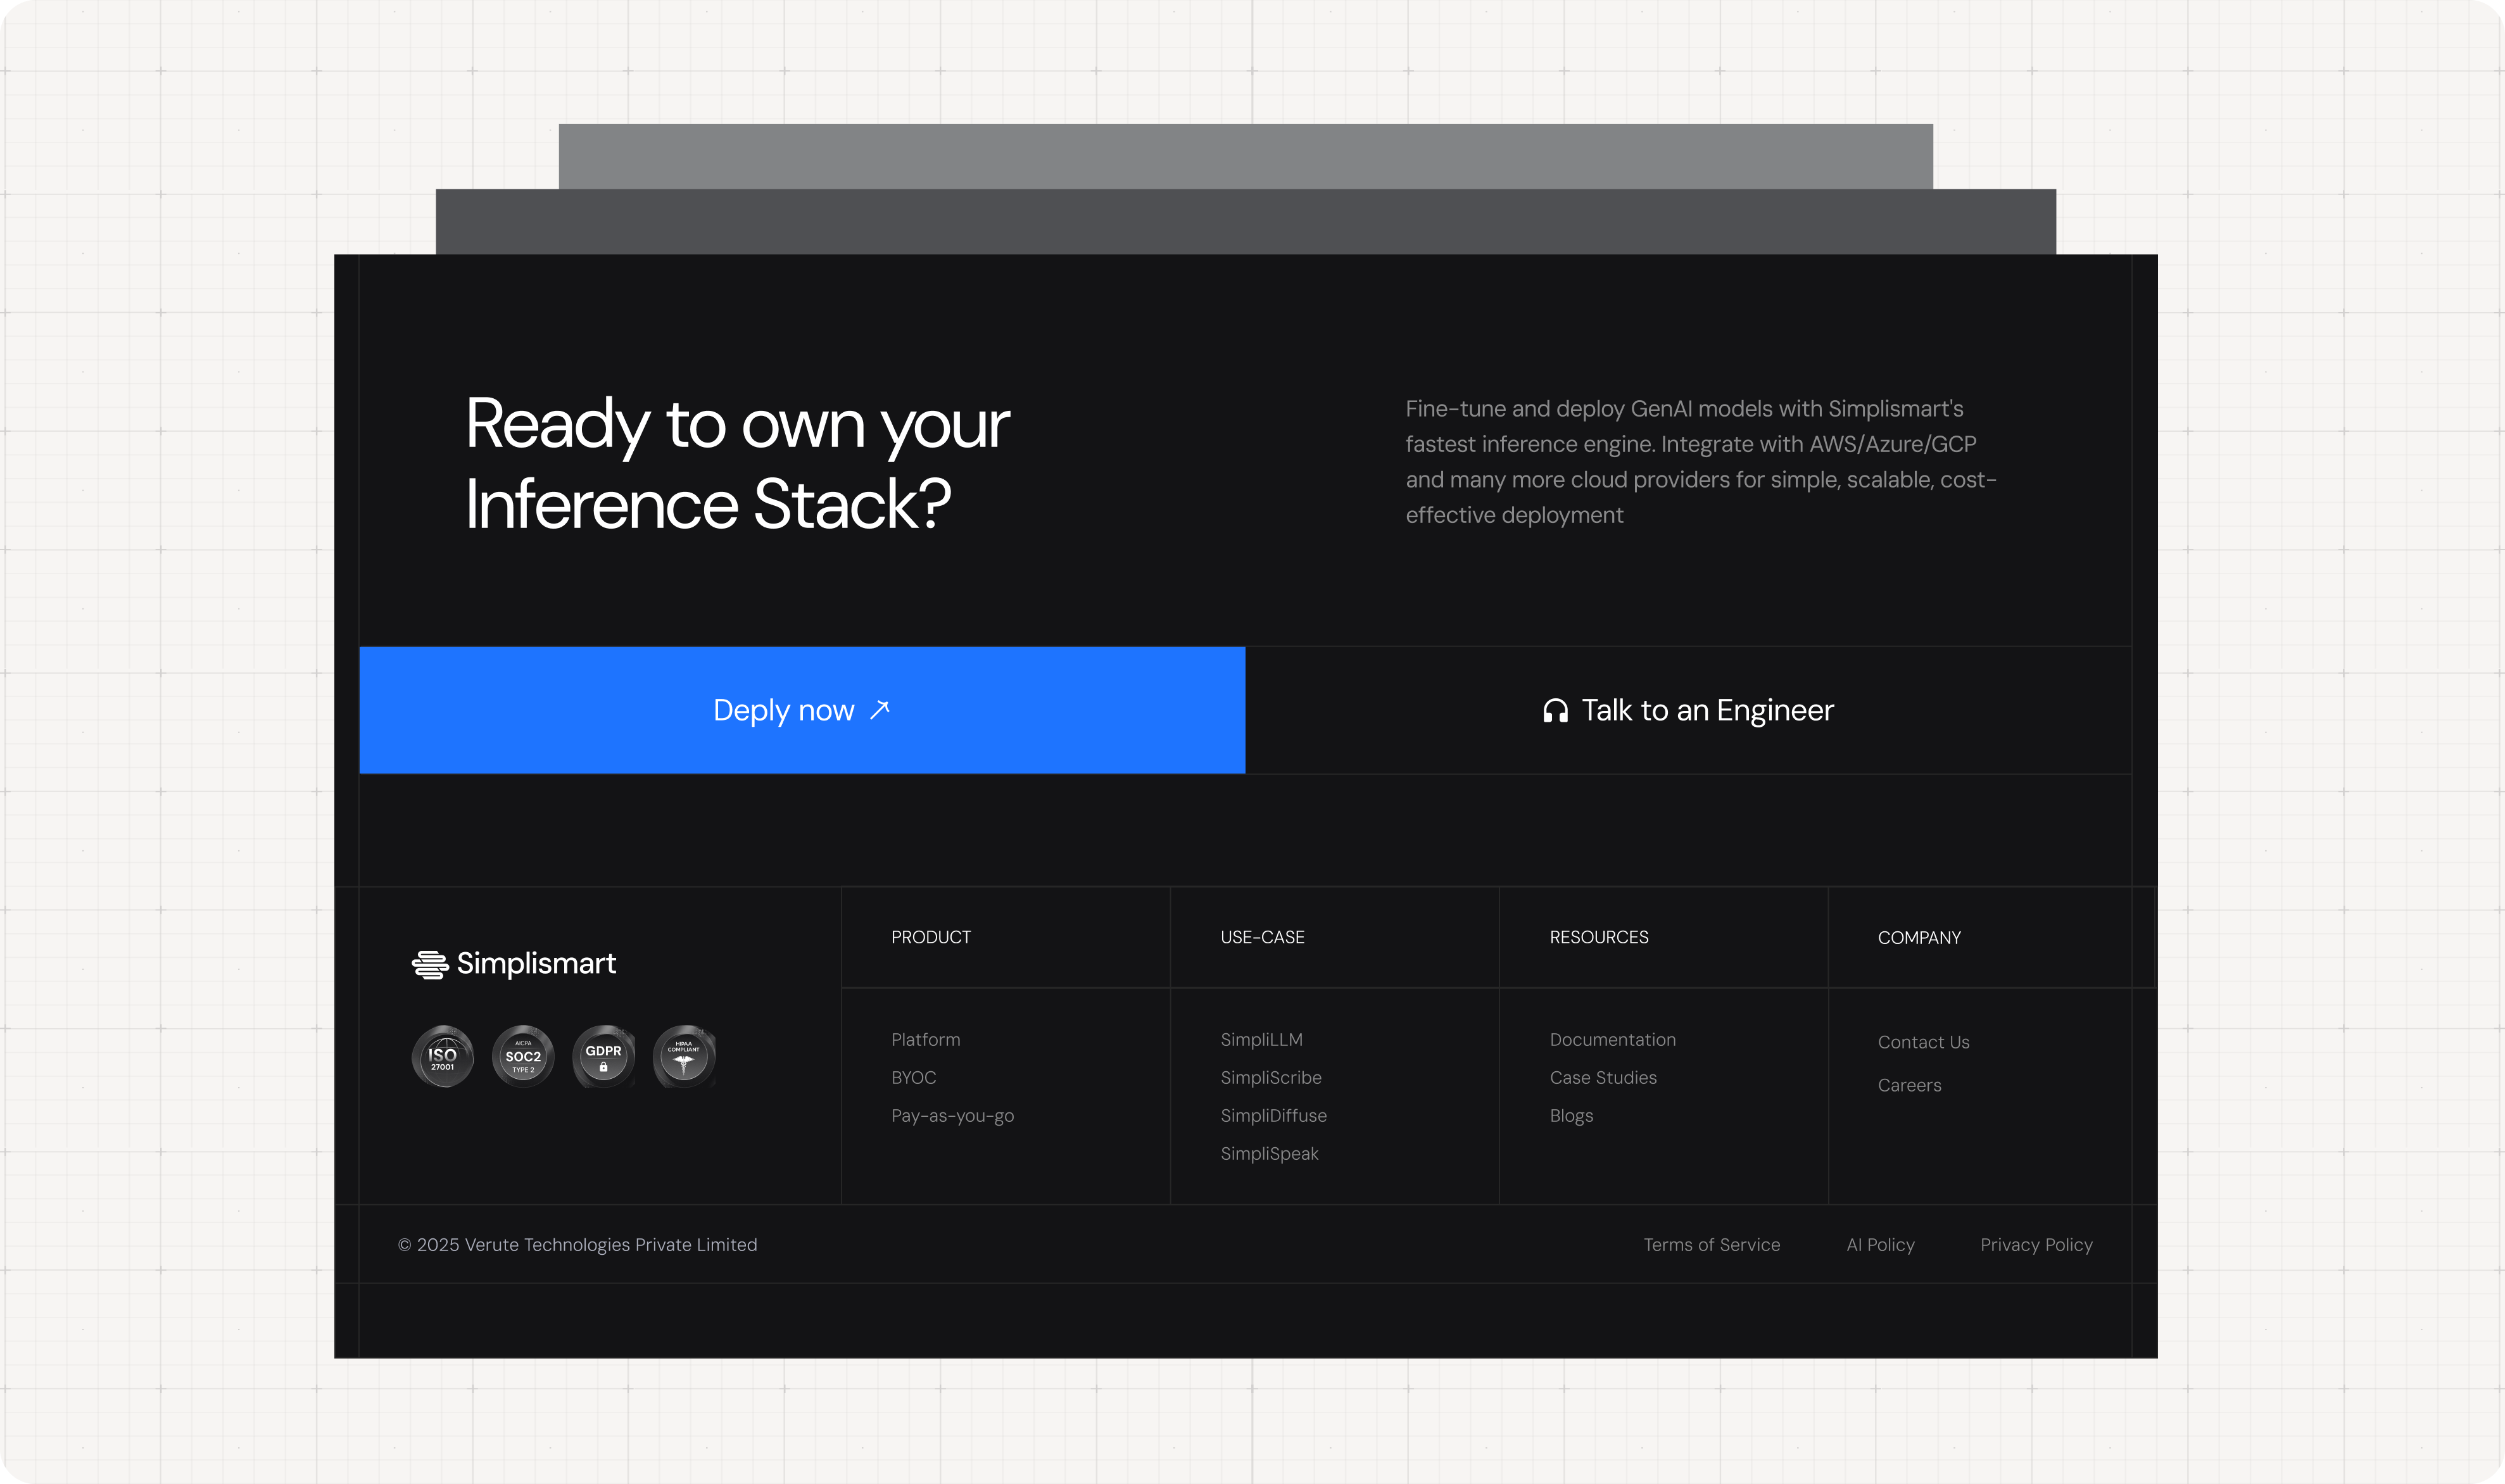
Responsive tablet and mobile interfaces for 
SimpliSmart brand poster and benchmark 04 · Impact & proof
Why technical honesty is the ultimate growth hack for developer tools
$7MSeries A led by Accel
30+Enterprise AI production customers
~$1MARR reached shortly after launch
Brand Strategy
Technical positioning, Benchmark communication
Visual Identity
Cobalt design tokens, Monospace code styling
Webflow Development
Interactive benchmark calculators, Interactive code tabs
Motion
Token streaming animations, Latency comparison graphs
Machine learning engineers have zero patience for marketing embellishment.
Shortcuts
- WWork
- CContact
- TLight or dark
- 8Random featured project
- ?This sheet